$ claude mcp add --transport http atlas-af https://mcp.af.uchicago.edu/mcp
what is needed behind this URL?
Claude Code · any model · any harness
› Using the atlas-af mcp, let's find a 1 TeV Higgsino in the Run 2 + Run 3 dataset.
Knowledge Bases & Agents for CERN · 2026‑10‑19
Building an MCP Platform for Scientific Computing
$ claude mcp add --transport http atlas-af https://mcp.af.uchicago.edu/mcp
what is needed behind this URL?
Claude Code · any model · any harness
› Using the atlas-af mcp, let's find a 1 TeV Higgsino in the Run 2 + Run 3 dataset.
Models and harnesses change week to week. That isn't what limits agentic workflows: it's reliable, secure access to the tools, data, and identities users already have.
Same prompt: “Where should my job outputs go?”
“Next to the job, in your home area.”
→ big files fill the home quota in minutes
“Big outputs to fast local scratch; small summaries in your backed-up home.”
→ same model, more context
Backup
Which model is best this month. The harness. The demo that goes viral. This layer moves fast and is not ours to own.
Context, identity, trust, packaging, and equitable access. Stable, hard, and squarely a computing job.
The claim
An LLM becomes useful the moment it knows your storage, scheduler, data, and identity, and safe only when those are real. That’s a computing-infrastructure problem, and it ports across experiments.
01
A loop that uses an LLM to decide a step, call a tool, read the result, repeat.
Model Context Protocol: a standard adapter exposing a service (Rucio, a notebook, a DB) as tools + live context any agent can call.
Static context loaded on demand: a reusable recipe (“how we do a fit here”).
The app that gives the agent hands: runs commands, wires up MCP servers, asks before acting (Claude Code, Codex, …).
Bundle skills + MCPs + agents → a plugin; a discoverable collection of plugins → a marketplace.
Backup
“It’s not about a smarter LLM — it’s about smarter infrastructure around it.” G. Watts, “Beyond Code Generation,” CHEP 2026
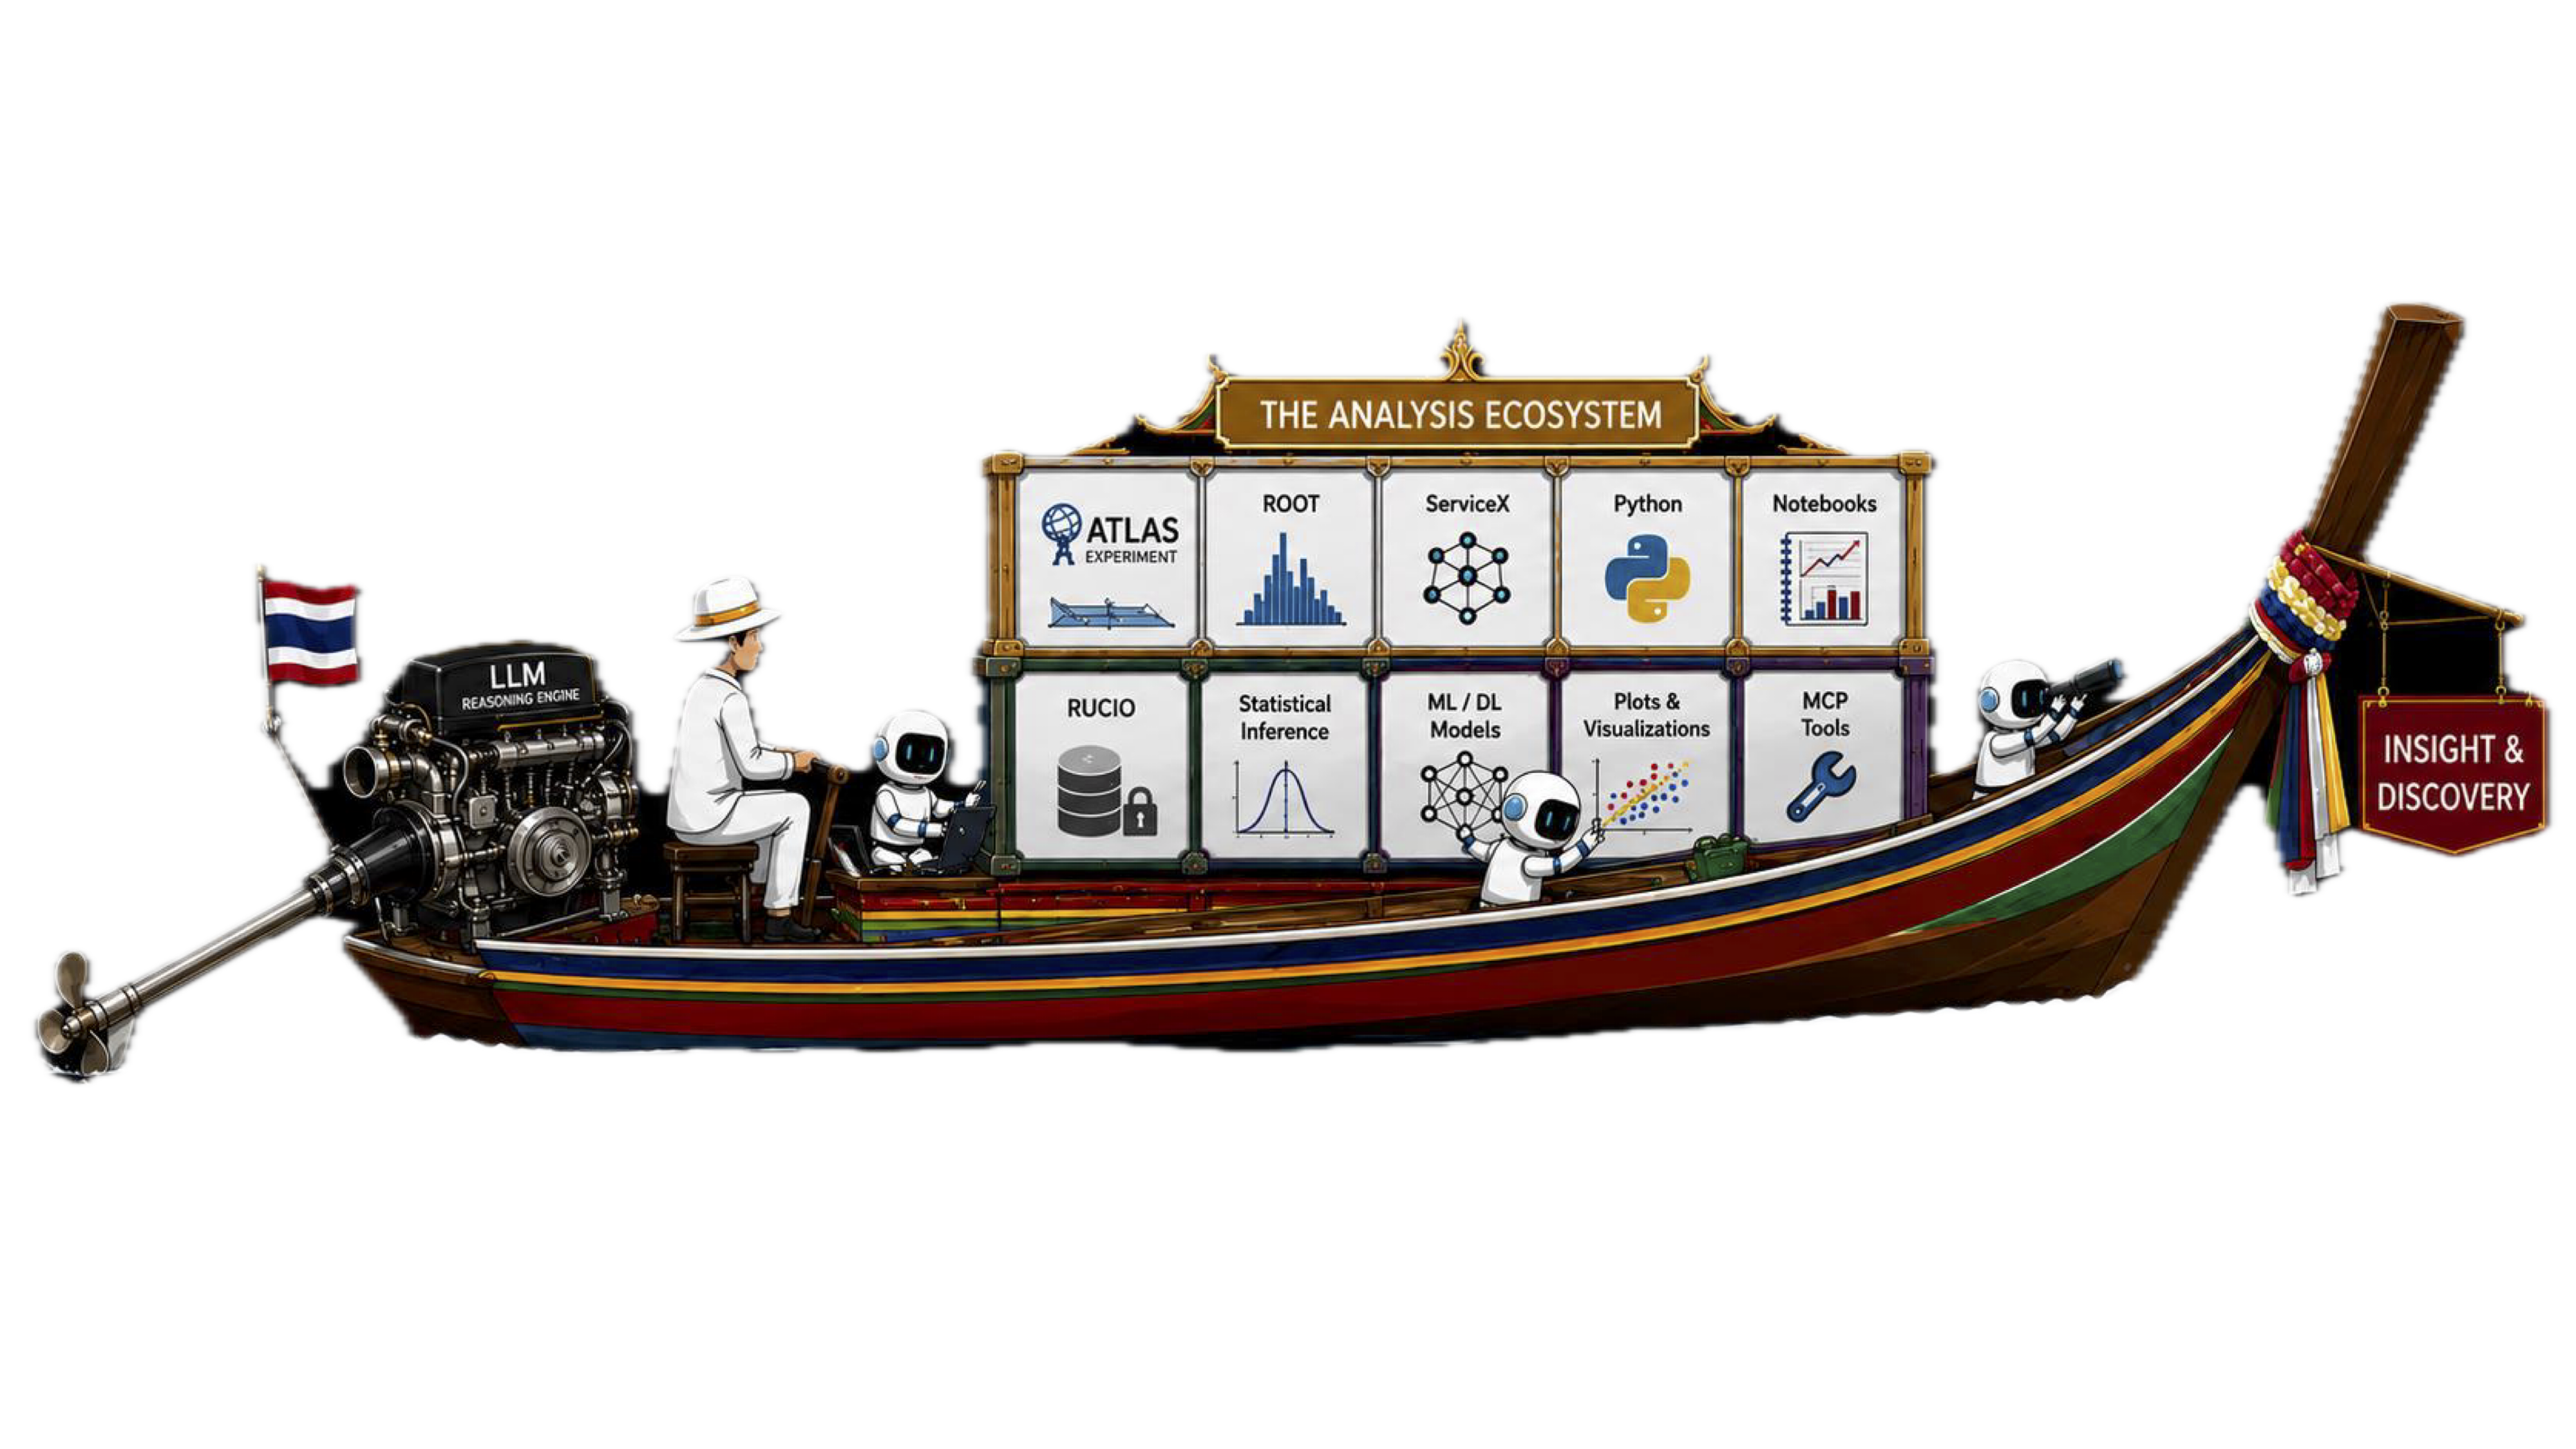
G. Watts’ CHEP 2026 slides · © Gordon Watts + AI
An open protocol connecting AI assistants (LLMs like Claude or Gemini) to the libraries, databases, and services scientists already use.
MCP (JSON-RPC)
⟷
Python · subprocess · REST
⟷
tools functions the LLM calls resources data it reads prompts reusable templates
from fastmcp import FastMCP
from rucio.client import Client

mcp = FastMCP("rucio")
client = Client()

@mcp.tool()
def list_dids(scope: str,
              pattern: str = "*") -> str:
    """Search datasets in a scope by wildcard.

    Use a narrow pattern; results are paginated.
    """
    return ", ".join(
        client.list_dids(scope, {"name": pattern}))

mcp.run()
rucio-mcp started from this barebones structure
list_dids, schema scope: str, pattern: str = "*", description = the docstringrucio.client, not the CLI: structured data in, curated text outfastmcp handles the JSON-RPC; you only write the functionThe facility lets my agent do things and learn things:
The USATLAS marketplace gives it know-how:
Backup
What actually happened
Our cluster agents confidently recommended Lustre tuning for a filesystem that is actually Ceph. Zero Ceph context. Plausible, fluent, and wrong.
The rule we adopted: ungrounded → silent. Context isn’t only what makes an agent useful; it’s what makes it safe to trust. This is why "who keeps the context true" is a real infrastructure question, not bookkeeping.
02
Running today at the UChicago AF
System-wide CLAUDE.md + safe-command allow-list, shipped by config management.
One-line install of facility + experiment skills.
rucio-mcp, ami-mcp, ATLAS OpenSearch. Rucio serves ATLAS, CMS, DUNE, ESCAPE.
condor-mcpSubmit, watch, and debug HTCondor jobs, as yourself.
servicex-mcpSubmit and track ServiceX transforms.
Start and drive a live AF notebook from any client.
Backup
escape site behind the hosted Rucio MCP: the bridge to the multi-science world (backup).It crosses experiments because of the architecture: the agent speaks intent, the facility wires the backend. Swap the playbook, keep the engine.
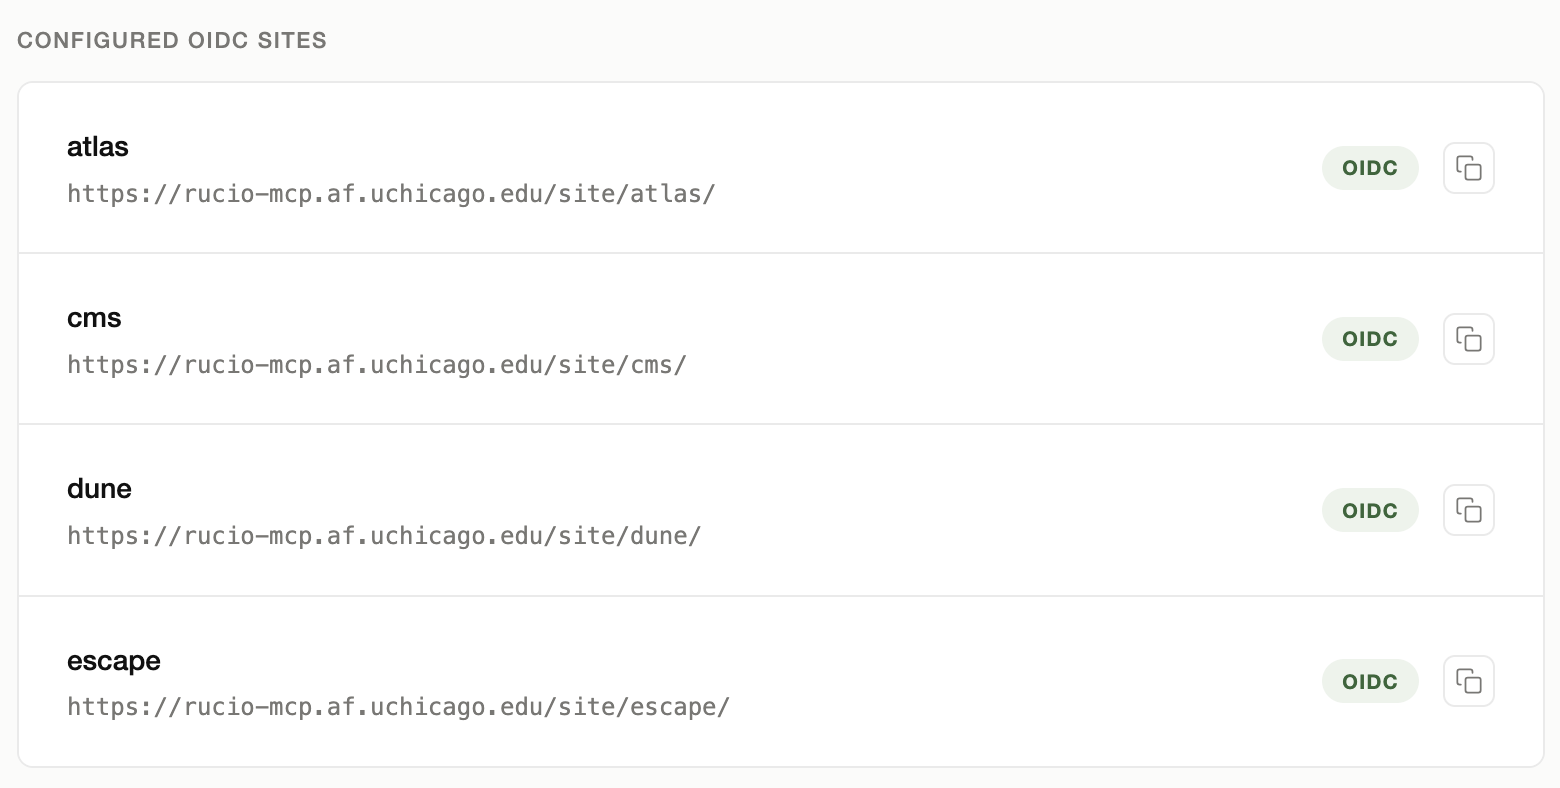
rucio-mcp.af.uchicago.edu: live OIDC sites for atlas, cms, dune, escape.
claude mcp add --transport http rucio-atlas \
https://rucio-mcp.af.uchicago.edu/site/atlas/No extra barriers for analyzers*; self-service access to what the facility already offers.
Never leak your credentials to the agent; never leak sensitive experiment data**.
Telemetry on usage: which tools get used, which don't.
*apart from having your own LLM assistant · **depends on the experiment’s guidance
live · the UChicago AF
$ claude mcp add --transport http atlas-af https://mcp.af.uchicago.edu/mcp
One prompt: submit an HTCondor job · start a Jupyter server · whoami · service catalog · AMI · Rucio · ATLAS OpenSearch · watch the job finish
This is analysis work. The same gateway is configured for operations: which services, tools, and permissions is Helm values.
03
Who is this agent acting for, what may it touch, and what must it never hold?
every MCP tutorial
→
→
the UChicago AF, in production
→
→
→
→
→
→
rucio-mcp · datasets, 45 toolsami-mcp · metadata, 11 tools + a query DSLaf-jupyterlab-mcp · notebooks, 22 toolsaf-filesystem-mcp · 4 read-only toolscondor-mcp · batch jobs, 25 toolsatlas-search-mcp-bridge · ATLAS OpenSearchservicex-mcp · columnar deliverypanda-mcp · coming soonaf-mcp-platform · gateway + brokervoms-token-service · grid proxieskrb5-token-service · Kerberoscondor-token-service · HTCondor IDTokensservicex-token-service · ServiceX tokensaf-credentials · shared verify/redeem libraryOne endpoint in front of the facility’s services. The LLM client never holds raw credentials; the broker authenticates the user, mints per-service credentials, and audits every tool call.
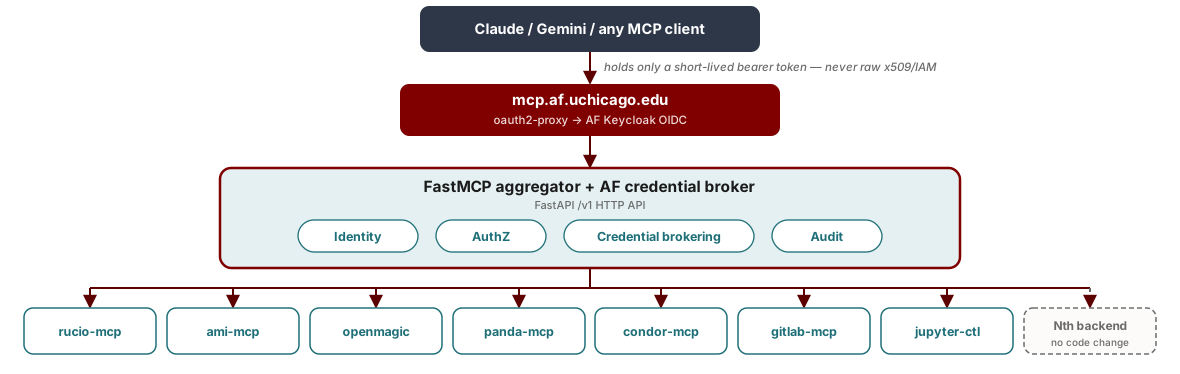
Identity, authZ, credential brokering, and audit in one place: the same boundary a facility wants in front of its services, with or without AI.
mcp-portal.af.uchicago.edu · live
The agent never holds a raw credential.
Group-based; denials audited.
Minted per service, deleted after use.
Infrastructure‑as‑Config: the next MCP server is Helm values on Kubernetes, never a change to the server.
one deploy per-VO auth in one process
clean isolation N servers to run
one identity token sprawl / choke point
We run the gateway: one identity, one place to authorize and audit. Next: how we handle token sprawl and the choke point.
FastMCP composition = one auth provider per server; that constraint drives a lot of the design.
1
Claude calls rucio-atlas_rucio_list_dataset_replicas with its personal access token
2
Gateway authenticates; groups and POSIX identity come from the IdP (Keycloak) on every call
3
Authorized once: this tool requires read_data; denials are audited too
4
Broker mints a JWT: aud=rucio-mcp-atlas (one service), exp = 10 min; it says who you are, not what you may do
5
rucio-mcp verifies that JWT, then redeems the VOMS proxy directly from the broker's vault
6
One Rucio call as the user; proxy deleted; one audit record, traced and metered
The user's token is never forwarded downstream; proxies and tickets never pass through the gateway.
@mcp.tool()
async def create_jupyter_server(
    image: str,
    name: str | None = None,
    cpu_cores: int = 2,
    memory_gb: int = 8,
    ...
) -> str:
    """...The server is always owned by the caller
    (from their verified broker identity) --
    there is no owner argument. ..."""
    claims = await get_broker_claims(ctx, verifier)
... create_notebook(owner=claims.unixname, ...)The principle
Do not expose dangerous parameters; derive them from verified identity.
tools/jupyterlab.py, abridged.e.g. a VOMS proxy or Kerberos ticket: fetch it → 0600 temp file → one backend call → delete it. The MCP server keeps nothing.
The user's token never goes downstream (the spec forbids it). Each hop gets a fresh short-lived JWT, valid for one service, expiring in 10 minutes.
e.g. only condor-token-service touches the Condor pool key; the broker is its only allowed caller, and it returns short-lived IDTokens.
bad: a token service deciding permissions
if "atlas-users" in token["groups"]:
    mint_ticket(user)
# a second copy of the access rules,
# trusting whatever the token claims
good: it only verifies who is calling
claims = verify(token, aud="krb5-token-service")
mint_ticket(claims["sub"])
# the gateway already decided permissions;
# this token proves who, from the broker
sketch; written into each token service's docstring (krb5 app.py)
Never store secrets in the MCP server. They live in a vault (OpenBao, here) behind the broker.
The only pod that sees home dirs and Globus passphrases. Runs voms-proxy-init impersonated; the privilege floor was found by trial on the live system.
Password → kinit → ticket; zero secrets at rest, passwords zeroed on every exit path. Rate limiter protects CERN's lockout counter, not itself.
Runs condor_token_create next to the pool key, which "must never reach the broker": it can mint any identity.
Why separate services
Different privilege floors (root+caps / none / one init container). Merging them forces the union of privileges onto everything. Each is a one-question audit: "did this call come from the broker?"
IdP groups → permissions (read or state change) → tools. Unknown tools are disabled, disallowed tools are not listed.
PATs carry a subset of your permissions, checked every call. 90-day default expiry, revocable, audited. A PAT can’t mint PATs.
Shell into a job: admins only. Rucio rule changes: manage_data. Some tools are excluded entirely. Backend annotations don’t grant access.
Skills, prompts, and allow-lists guide the agent. The server-side check enforces, and denials are audited.
A skill tells the agent what it should do; the gateway decides what it can do.
authorization/base.py, api/tokens.py, mcp/instructions.py · ↓ the config and the audit recordDeep-dive
entitlements:
  group_permissions:
    /connect/atlas-af: [read_data, read_files,
      submit_jobs, manage_jobs, manage_jupyter, ...]
    /connect/uchicago/admin: [..., exec_jobs,
      manage_data, admin]
    __authenticated__: [read_monitoring]
aggregator:
  services:
    - name: condor_service
      exclude_tools: ["advertise_to_collector"]
      required_permission:  # no __default__:
        submit_job: submit_jobs  # new tools
        remove_job: manage_jobs  # ship off
        exec_in_job: exec_jobs
        query_jobs: read_monitoring
excerpt of the deployed Helm values (UChicago AF)
Groups come from the directory, never from the token’s claims.
Backup
Find data, generate code, submit, recover, fit. Low autonomy, high convenience.
Cluster health reports, hold-reason triage, drafted user emails, human-approved.
Config/runbook copilots in the privileged lane; trust earned, actions gated.
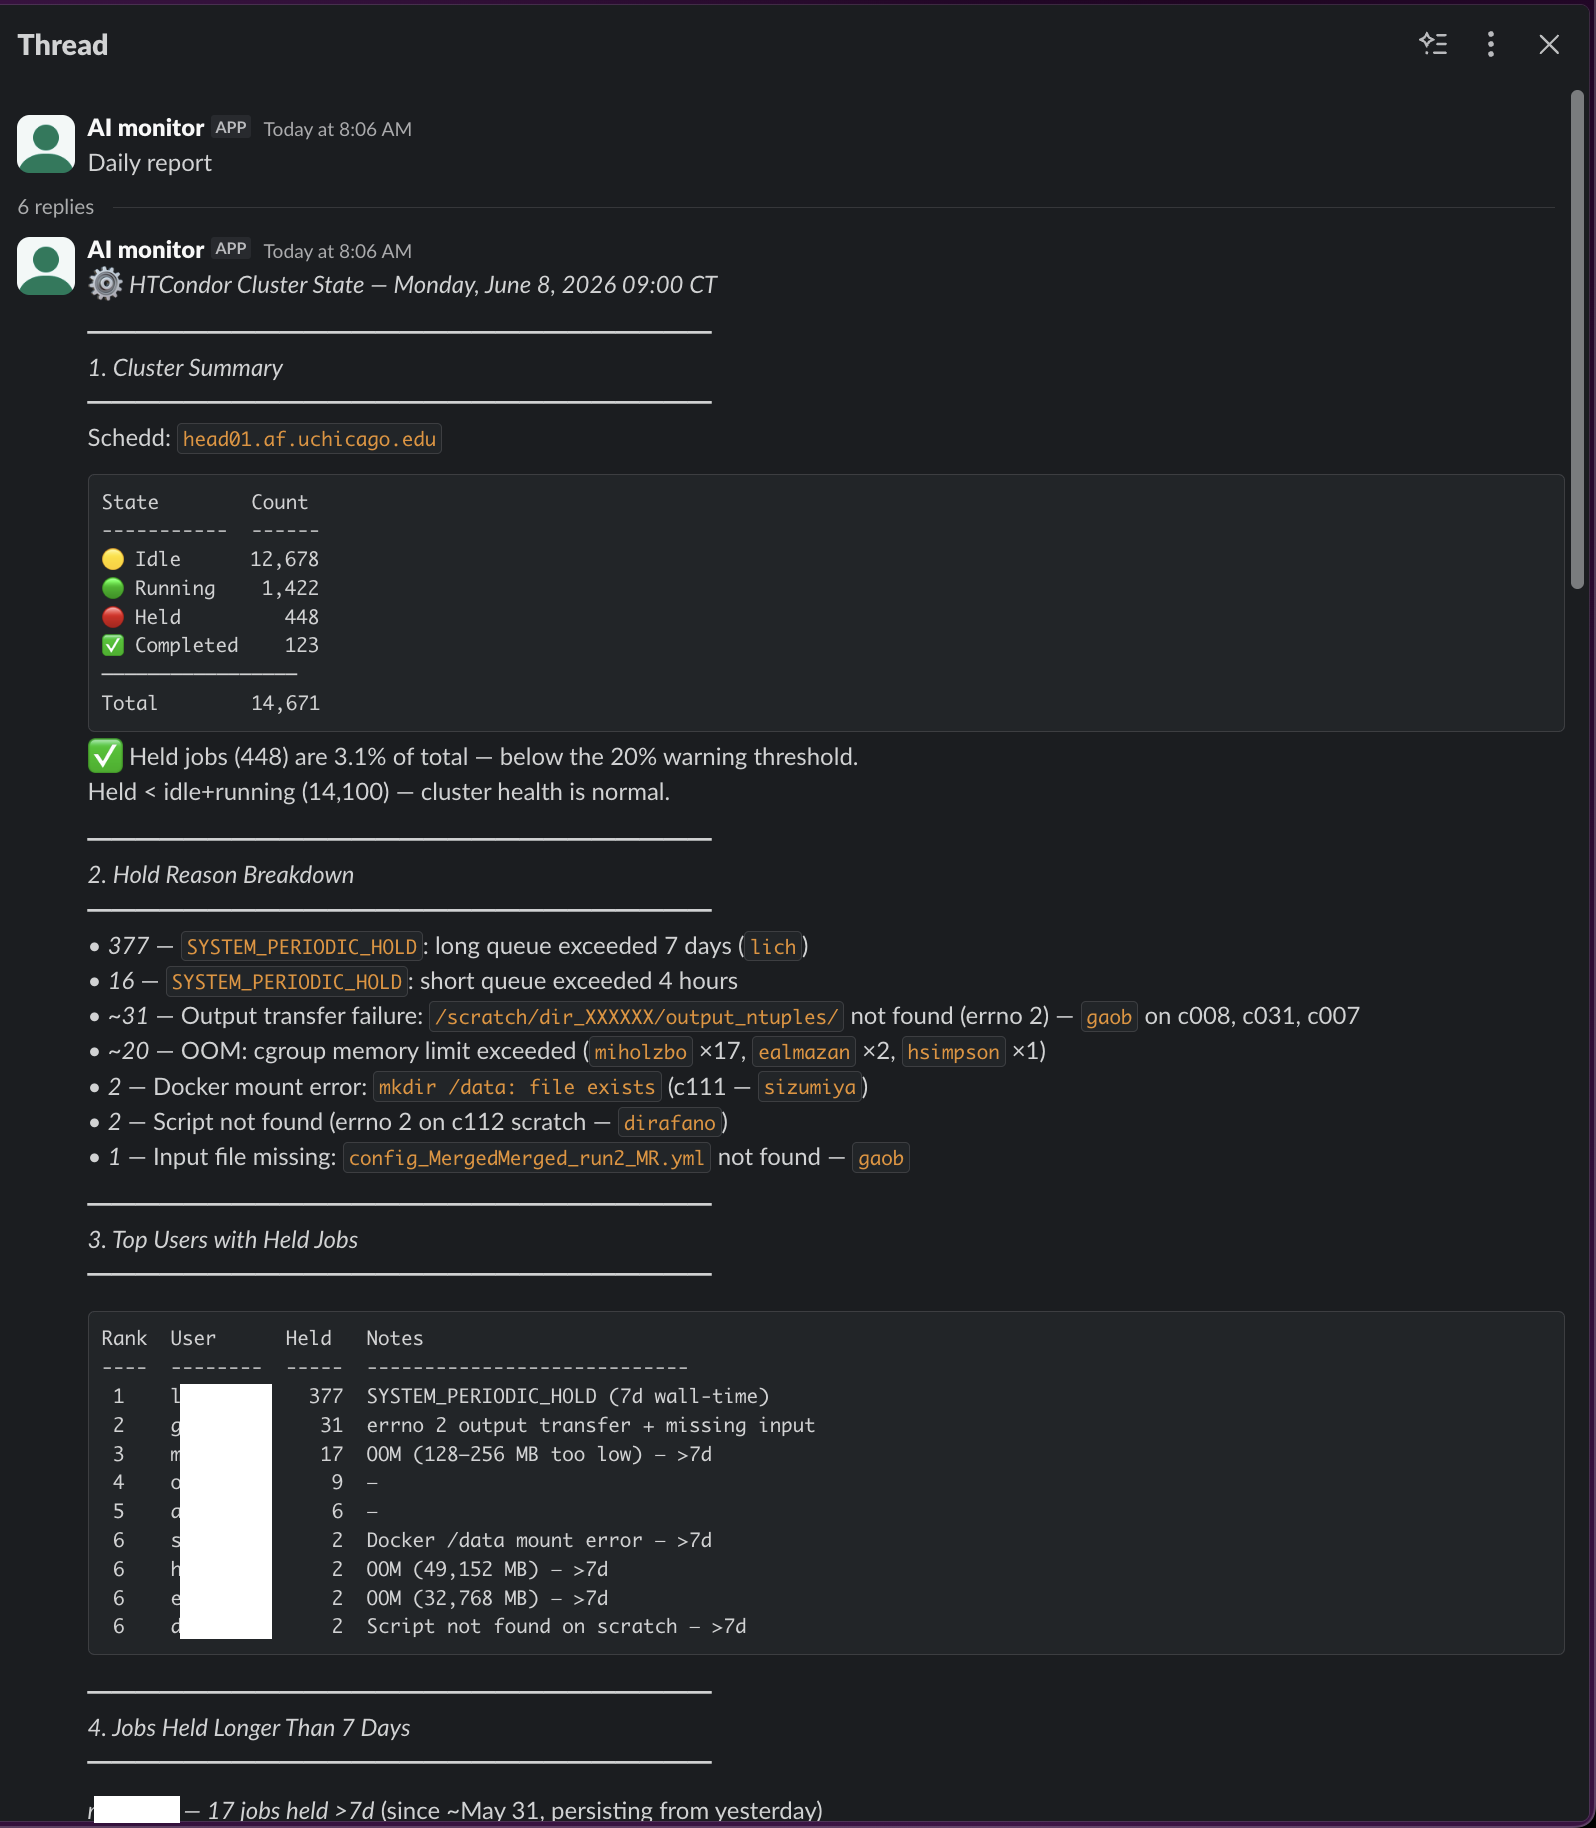
Morning report: 448 held of 14,671 (3.1%)
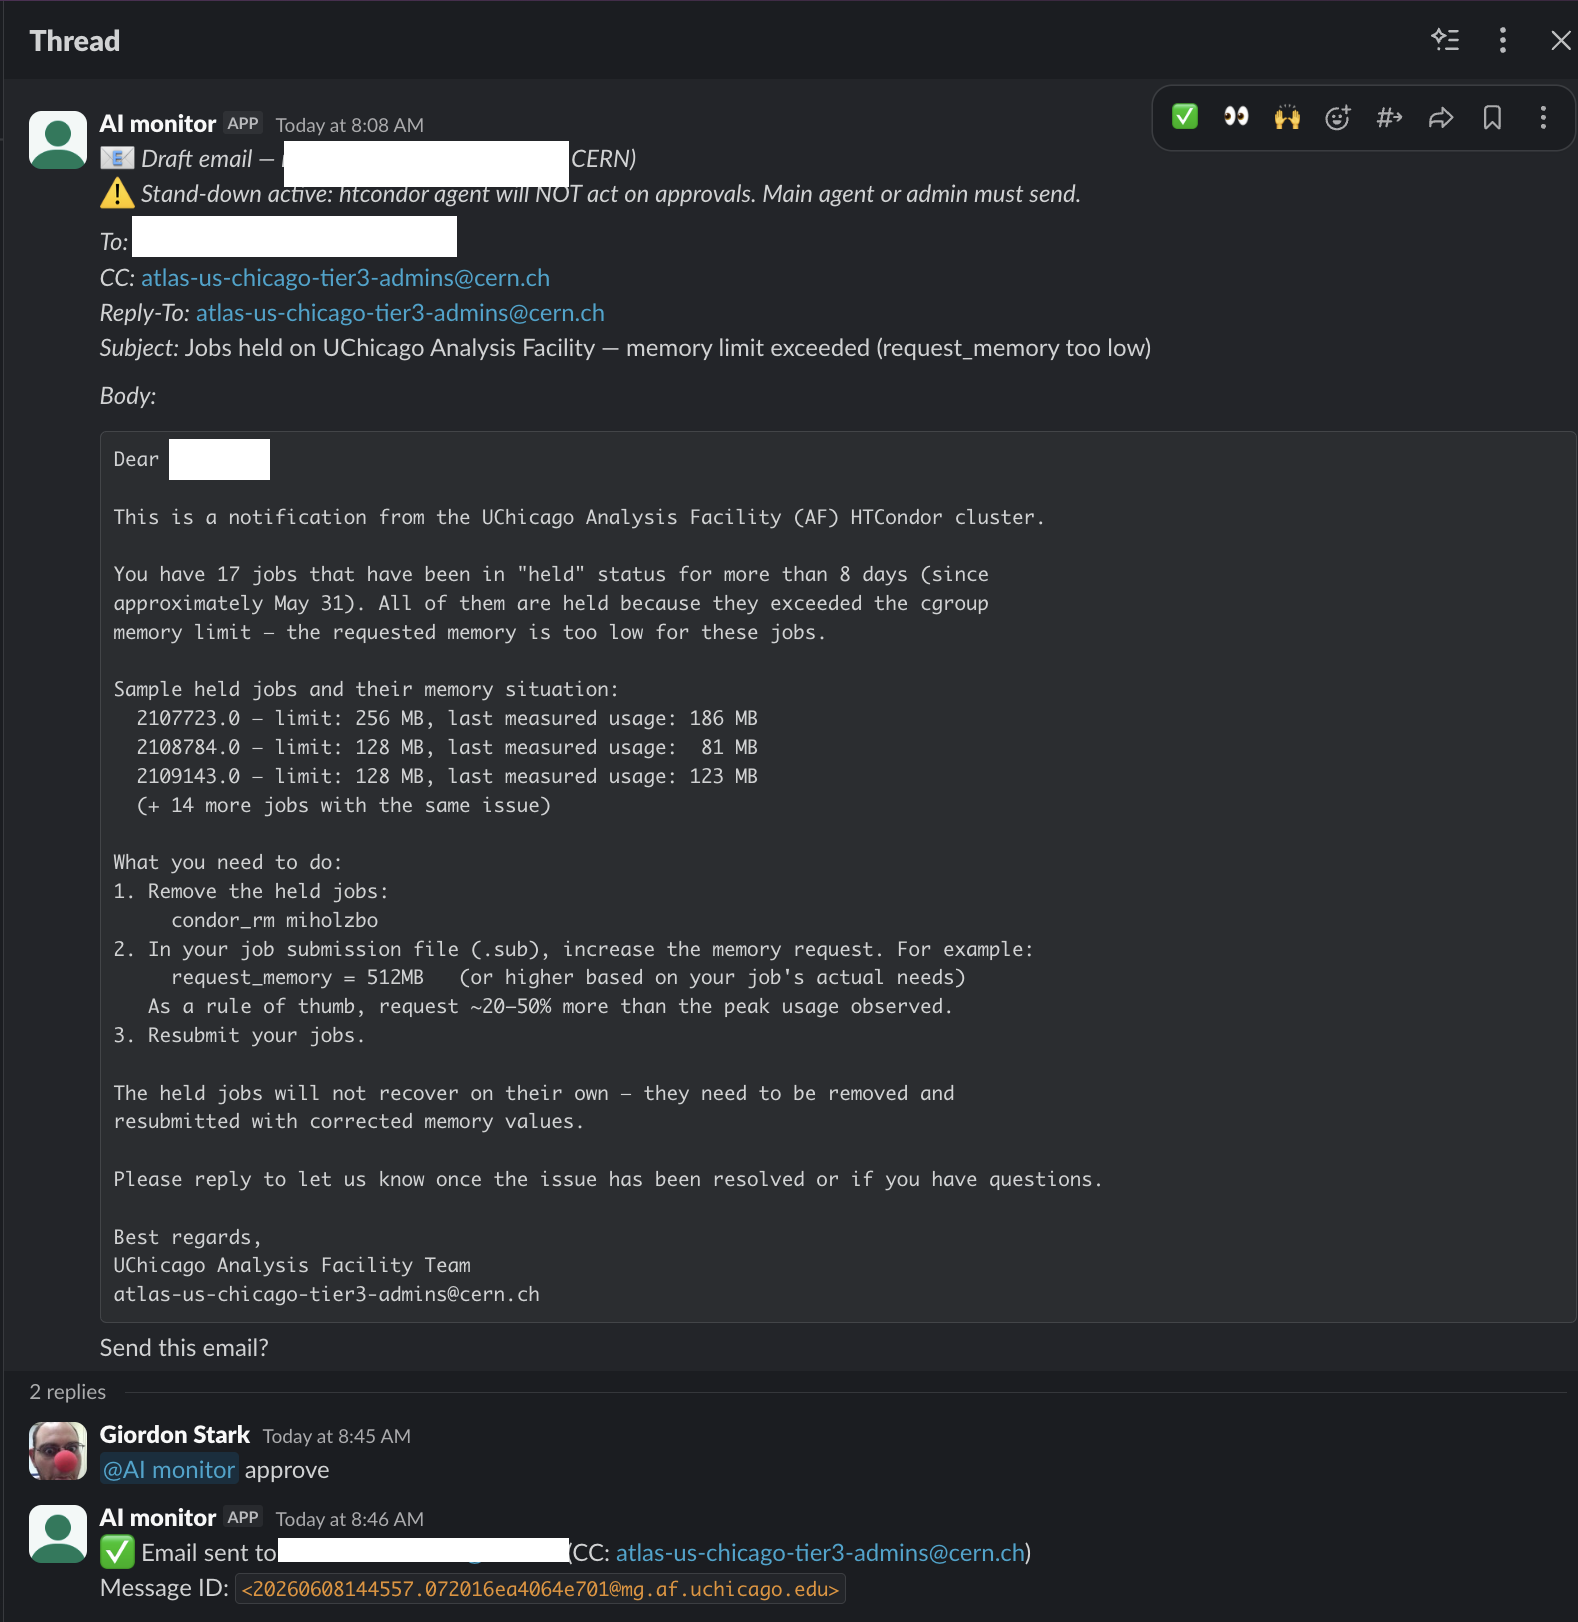
Drafted fix → human types “approve” → sent
Nothing in the gateway is analysis-specific. Services, tools, and which groups may call them are Helm values, so each layer gets its own autonomy and blast radius by config, not new code.
Backup
Anomaly detection over existing monitoring + accounting: reactive firefighting → proactive, root-cause alerting. Accounting-record integrity as a contained first win.
The analysis describes the columns it will read; drive XCache/XRootD prefetch from that, not workflow-blind heuristics.
Forecast runtimes, right-size over-requests, pick MIG profiles, route across heterogeneous/federated resources. The scheduler still places; AI shapes the inputs.
These sit upstream of every experiment (a Tier-1 concern), so even modest gains compound across the whole community.
The same intent-tool abstraction sits over a KM3NeT reconstruction job or a Virgo data-quality pipeline as readily as a Coffea columnar read: the backend changes, the agent’s interface doesn’t.
Lessons learned
Design decisions baked into the AF MCP Platform
rucio-atlas_*, fs_*)tools/list, so the gateway mints one just to enumeratetools/list instead of every call failingDeep-dive
bad: the raw API dump
{"logicalDatasetName": "mc23_13p6TeV.601229...",
 "crossSection": "0.729", "crossSection_unit": "nb",
 "genFiltEff": "1.0", "kFactor": "1.0",
 "principalPhysicsGroup": "...", "prodsysStatus":
 "...", ...95 more fields, duplicate rows...}
every field, no units help, and the same for each of 50 datasets
good: markdown-friendly, LLM-friendly
**mc23_13p6TeV.601229** (PhPy8EG ttbar) · VALID
Cross-section: 729 pb (0.729 nb × 1000)
Events: 2M · k-factor: 1.0

---
**Next steps:**
- ami_get_dataset_prov for provenance
- rucio_list_dataset_replicas to locate copies
~15 curated fields, units converted in the open, follow-up tools named
The docstrings keep getting fixed against each tool's actual behavior, to teach the LLM how to use it correctly. The LLM reproduces examples verbatim, so a doc bug is a behavior bug.
Deep-dive
bad: what the agent sees by default
Traceback (most recent call last):
  File ".../replicaclient.py", line 158, ...
rucio.common.exception.DataIdentifierNotFound:
  Data identifier 'user.gstark:mydata'
  not found
a dead end: nothing tells the agent what to try next
good: what rucio-mcp returns instead
Error: Data identifier
'user.gstark:mydata' not found

**Recovery:** The DID does not exist in
Rucio. Use `rucio_list_dids` with a
wildcard pattern to search for it.
returned to the agent, not raised into server logs; the next tool is named
Empty results carry the same routing hints. The error categories also feed my monitoring, so I can see which tools confuse the agent.
MCP results have an isError flag so clients can tell failure from success. I didn't set it at first; do both.
tools/_helpers.py (classify_error).Deep-dive
bad: rucio_list_files("mc23..."), unbounded
mc23_13p6TeV:file_000001.root
mc23_13p6TeV:file_000002.root
mc23_13p6TeV:file_000003.root
... 499,997 more lines ...
one call floods the LLM's entire context window, and the server downloaded all 500k names to do it
good: capped, and the output says so
mc23_13p6TeV:file_000001.root
... 49 more ...

---
Showing 50 results (offset=0).
Pass `offset=50` to see more.
a hard server-side limit, announced in the output, with the way to continue spelled out
And cap the server's work too: rucio-mcp once fetched that whole 500k-file container upstream just to serve one 50-row page. Paginate the upstream iterator, not just the output.
tools/_helpers.py (paginate_iter).| Tried | Discovered | Ended with |
|---|---|---|
| Rust CLI wrapper | parsing text tables is fragile | Python + native client |
| Returning raw API rows | noise swamped the LLM | curated fields, converted units, next steps |
| Docstrings written from memory | the LLM reproduced broken examples verbatim | docstrings tested against the live service |
| Stateful MCP sessions, 2 replicas | cross-replica "Session terminated" | stateless HTTP (now the spec default) |
| Dynamic Client Registration | you maintain a database of client ids, and a restart orphans them all | CIMD (later adopted by the spec) |
| Groups inside JWT claims | revocation waits for token expiry | live IdP lookup, a real kill switch |
04
Orchestration, routing, guardrails. Written once. Model- and experiment-agnostic. shared
Which MCPs/backends, the system prompt/CLAUDE.md, the knowledge corpus. swappable
A new facility or experiment writes only the playbook.
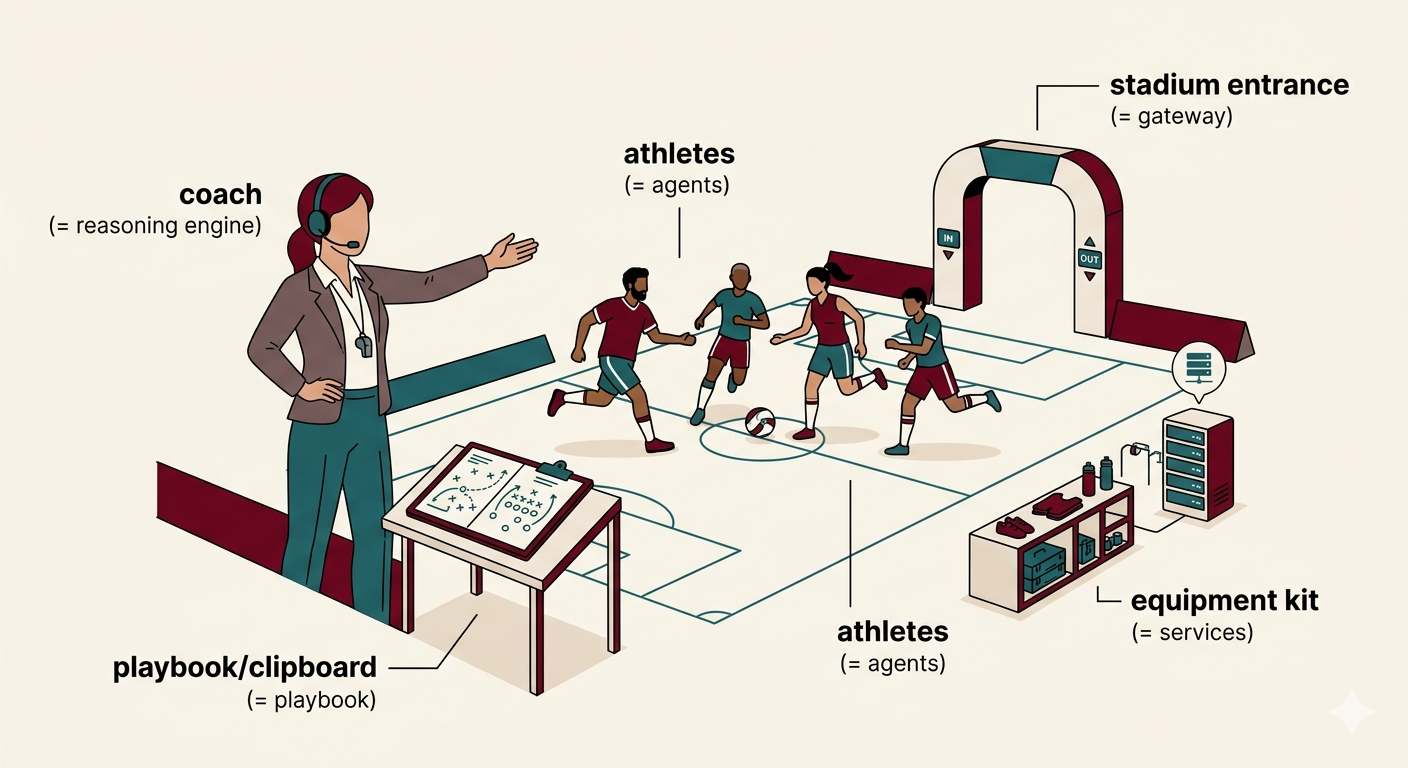
Coach = engine · playbook = playbook · athletes = agents · equipment = services · stadium = gateway
Stop re-developing the same agentic tooling in parallel, across facilities, experiments, and sciences.
Backup
data_tool“get this dataset + metadata”
transform_tool“turn inputs into histograms”
batch_tool“run across the cluster”
inference_tool“fit and get a limit”
Rucio · dCache · Open Data
coffea · uproot · ServiceX
HTCondor · Slurm · Dask · REANA
pyhf · cabinetry · RooFit · SBI
inference_tool privileges no single fitter: HS3 (HEP Statistics Serialization Standard) + pyhs3 are the bridge between pyhf and RooFit.
The agent never names “coffea” or “condor.” That indirection is exactly what lets the same agent move between facilities and experiments.
Interoperable tool interfaces are likely to matter more than LLM-specific integrations.
| My choice | MCP 2.0 spec (2026-07-28) | Verdict |
|---|---|---|
| Stateless HTTP, state as explicit handles | protocol sessions removed | compliant / anticipated it |
| CIMD instead of Dynamic Client Registration | DCR deprecated for CIMD | compliant / anticipated it |
| Tools only; no sampling, roots, logging | all three deprecated | compliant / anticipated it |
| Exchange tokens, audience-validate everywhere | token passthrough forbidden (MUST) | compliant |
outputSchema on tools that return data | structured content recommended | compliant; fixed since PyHEP.dev |
| Read-only / destructive tool annotations | annotations recommended | compliant; fixed since PyHEP.dev |
Backup
escape site. The bridge is built; the agentic layer can sit on top of the VRE.# escape.cfg, a real shipped site config
[client]
rucio_host = https://vre-rucio.cern.ch
auth_host = https://vre-rucio-auth.cern.ch
oidc_issuer = escape
oidc_audience = rucioBring the credential-brokered gateway + portable playbooks to the ESCAPE VRE, so the same tooling serves LHC and astroparticle science, built once.
Backup
Analysis facilities are the visible end. The bigger leverage is the shared services upstream of every experiment (data origins and caches, accounting, identity), the Tier-1 / OSG-LHC layer. The goal: move AI from passive observation toward trustworthy, measured autonomy.
anomaly detection on telemetry + accounting integrity
token-exchange from WLCG/SciTokens to AI backends
a conformant facility-MCP interface, WLCG-style
A shared commons across US and European facilities, each contributing its perspective instead of re-inventing the stack.
How do we evaluate, and secure, an agent that acts?
How should facilities expose context?
How do we share context between facilities, and keep it true?
What makes an environment truly portable, and maintainable?
Who pays for inference, and is that fair?
What becomes standard across sciences?
Design the interface for the model; design the architecture for the credential.
Backup
The open question: who hosts that commons across experiments and facilities, and who keeps it true?
The client_id is a URL the server fetches: no registration database, and the facility picks which domains it trusts. Watch for SSRF.
why · mechanics · live trace
Swap permanent SSH keys for short-lived federated credentials. An agent with a shell inherits minutes, not a key that lives forever.
Pods, then bubblewrap off Kubernetes, then eBPF policy, then human-gated privilege. Harnesses can advise, but can't reliably hard-deny.